SEO & AI Search
Perplexity SEO: How to Get Cited in Perplexity Answers, With Anobee's Own Citation Data (2026)
By Bibek Thapa · Updated · 15 min read
Quick Answer
Perplexity SEO is the work of getting a page cited as a source in Perplexity's answers. Three things matter most: Perplexity leans heavily on Google's top 10 (82% URL overlap in Semrush's 2025 study), its crawler must be able to reach you (check Cloudflare, not just robots.txt), and answer-first pages are easier to quote. Track the URLs it cites with a fixed prompt set.
Table of ContentsOn this page
- What Perplexity SEO is
- How Perplexity chooses sources
- What Anobee's own Perplexity SEO test shows
- How to track the source URLs Perplexity cites
- The FETCH checklist for Perplexity SEO
- 7 Perplexity SEO steps to get cited
- What changed in this guide
- Bottom line on Perplexity SEO
- Frequently Asked Questions
- Sources and References
Key Takeaways
- Perplexity has two fetchers: PerplexityBot follows robots.txt and feeds its search index; Perplexity-User fetches on request and generally ignores robots.txt.
- Perplexity tracks Google closely: 82% URL overlap with Google's top 10 in Semrush's July 2025 study. Ranking in Google is most of the job.
- Since July 2025 Cloudflare blocks AI crawlers by default on new domains. On Cloudflare, that setting decides your Perplexity visibility before content does.
- Across four runs of Anobee's fixed-prompt test, Perplexity cited anobee.com every time but kept at most two pages between runs.
- Perplexity's Links tab lists every source with its full URL. Record those URLs per prompt and per run, not just whether you were cited.
- The FETCH checklist (Fresh, Extractable, Trustworthy, Crawlable, Hyper-relevant answer first) is a pre-publish routine, not a ranking formula.
This Perplexity SEO guide rests on four kinds of evidence. Three are public: Perplexity's crawler and API documentation, two Cloudflare reports that change the crawlability advice, and Semrush's overlap study. The fourth is Anobee's own. Since September 2026, Anobee has run the same citation prompt through Perplexity four times. Every source URL was recorded, most recently on 14 October.
What Perplexity SEO is
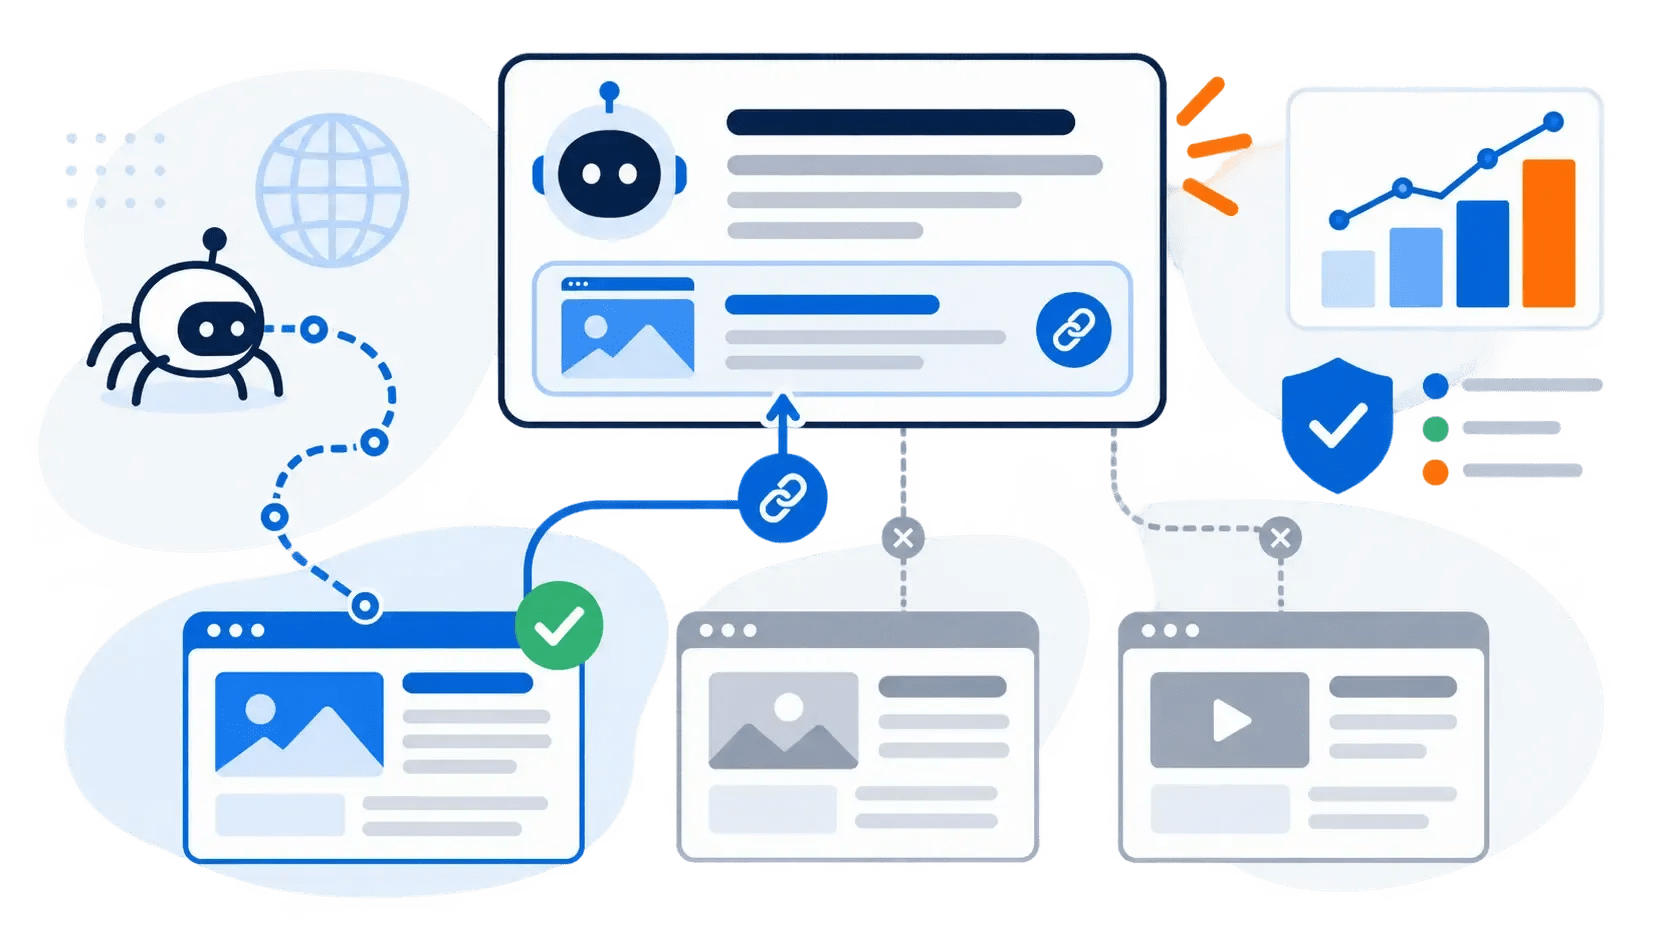
Perplexity does not show ten links. It runs a search, reads a set of pages, writes one answer and attaches source links to the sentences it took from them. There is no position two. A page is either in the source set or it is not. The goal of Perplexity SEO is to be in that set for the questions your readers ask.
The audience is not small. Perplexity's CEO said the service handled 780 million queries in May 2025, about 30 million a day, growing more than 20% month over month [3]. Perplexity does not publish regular user counts. Later figures you see are third-party estimates; the May 2025 number is the last one the company stated itself.
Two properties of Perplexity shape everything below. It fetches pages live rather than answering from a fixed training set, and it cites visibly, which means you can measure it.
How Perplexity chooses sources
Perplexity's retrieval tracks Google's more closely than the other AI engines in the same study. Semrush's July 2025 study of 5,000 keywords found that Perplexity's cited sources had over 91% domain overlap and 82% URL overlap with Google's top 10 results [2]. Google's own AI Mode managed roughly 54% domain and 35% URL overlap in the same study, and ChatGPT showed the least alignment of all [2].

That single finding reorders the usual Perplexity SEO advice. Four out of five URLs Perplexity cites are already in Google's top 10 for the query. So the main path into Perplexity's answer is the one you already know: rank in Google. Formatting, freshness and structure decide which of the retrieved pages get quoted. They rarely get a page retrieved that Google does not rank.
What Perplexity says about its own crawlers
Perplexity documents two fetchers, and they behave differently [1]:
| Fetcher | What it does | robots.txt |
|---|---|---|
| PerplexityBot | "Designed to surface and link websites in search results on Perplexity." Not used to crawl content for AI foundation models. | Follows it. Perplexity recommends allowing it. |
| Perplexity-User | Visits a page when a user asks a question, and may link to it in the answer. | "Generally ignores robots.txt rules," because a user requested the fetch. |

Both publish their IP ranges as JSON files, and Perplexity says changes to access settings can take up to 24 hours to apply [1]. The practical reading: blocking PerplexityBot removes you from Perplexity's own index, which is where most citations come from. It does not stop a user-triggered fetch. Allowing it costs little, because the bot is not a training crawler.
What the studies can and cannot tell you
Third-party citation studies are useful for direction and unreliable for precision. Analyze AI's May 2026 analysis covered 83,670 citations across ChatGPT, Claude and Perplexity. Pages in a question-and-answer or direct-answer format reached a top-3 citation slot 55% of the time, against a 31% average [6]. Freshness also correlated with placement [6]. It is a vendor study with its own tracking tool behind it. Treat the direction (answer-first pages do better) as credible and the exact percentages as that vendor's sample.
No study has established a weighted list of "Perplexity ranking factors". Any table that assigns percentages to domain authority or freshness is a guess dressed as data.
What Anobee's own Perplexity SEO test shows
Each run sends the same prompt to Perplexity: "Search the web for Anobee and cite the sources you use". Each session is fresh and signed out, the mode is Search, and every source URL is recorded. The same prompt goes to ChatGPT, Gemini and Google AI Mode; the full method and cross-product results are in the AI Citation Index. The Perplexity column alone is instructive for Perplexity SEO.
| Run | Perplexity cited anobee.com | Distinct Anobee URLs | Retained from previous run | Notes |
|---|---|---|---|---|
| 9 Sep 2026 | Yes | 7 | First run | Mixed in two unrelated lookalike domains |
| 14 Sep 2026 | Yes | 4 | 0 of 7 | Entity correct; source panel carried off-topic pages |
| 18 Sep 2026 | Yes | 11 | 1 of 4 (homepage) | 15 sources: 11 Anobee pages, one author site, three unrelated |
| 14 Oct 2026 | Yes | 10 | 2 of 11 (homepage, entity guide) | 10 sources, all anobee.com; no unrelated pages |

Four patterns hold across the four runs.
A small, new site gets cited. Anobee began publishing in mid-2026 and was in Perplexity's source set on every run. Domain age was not the barrier.
Presence is stable, source choice is not. Perplexity cited the site every time. Between runs it kept none, one, and then two of the previous pages. If you track only "were we cited", you will see a flat line. Track which URLs and you will see churn.
Perplexity retrieves broadly and cites narrowly. On 18 September the source list held 15 entries. Only five of the eleven Anobee pages were linked inline in the answer text. The source list is the retrieval set; the inline links are the citations a reader sees first.
Noise comes and goes. For example, the September runs each carried unrelated pages, such as a Yahoo article about power outages and a Reddit thread about watches. None reached the answer text. The October run carried none at all. Perplexity described Anobee correctly every time, so entity accuracy and source tidiness are separate properties.
The October run added one detail worth noting. Perplexity's answer described Anobee's own citation test and its September results. To do it, it cited the two AI Citation Index pages and this guide. Published, specific first-party data became the thing Perplexity reached for when asked about the site.
How to track the source URLs Perplexity cites
For Perplexity SEO, the URL list is the measurement that matters, and Perplexity shows it if you know where to look.
- Run the prompt in a clean session. Use a signed-out browser or a fresh session, and note the mode (Search, in Anobee's runs). A signed-in account brings its own history, which makes runs harder to compare.
- Open the Links tab. Above every answer there are tabs for Answer, Links and Images. The Links tab lists every source Perplexity used, each with its site name, full URL, page title and a short description.
- Read the chips in the answer. In the Answer tab, small source chips follow each sentence. A chip marked +1 or +3 groups more than one source. These are the inline citations, the ones a reader actually sees beside a claim.
- Record per prompt, per run. Note the date, the exact prompt, the mode, whether you were signed in, each source URL, and whether that URL also appeared inline. A spreadsheet is enough. The method for checking AI citations has a recording template.
- Normalise before comparing. Strip tracking parameters, ignore fragments and merge trailing-slash variants, so one page does not count twice. Then compare runs by page, not by raw link.

If you track many prompts, Perplexity's API is the faster route. Perplexity ended support for Sonar Chat Completions on 27 September 2026 and recommends its Agent API instead. In Agent API responses, the sources appear in a search_results output item. Its results array gives each source's url, title, snippet and date, and the answer text carries numbered markers pointing to them [9]. The API is not the consumer app, so treat its source lists as a related signal rather than a copy of what a person sees.
Paid trackers automate the same steps. Whatever you use, check that it records URLs, not only brand mentions, and that it shows its prompts and run dates.
The FETCH checklist for Perplexity SEO
FETCH is Anobee's pre-publish routine for pages that should be citable. It is a checklist, not a ranking formula. It applies to Google's AI features as much as to Perplexity: Google describes optimising for its generative AI features as "still SEO" [7].
- F, Fresh. Update pages on fast-moving topics and show a real "last updated" date. Change the date only when the content changed.
- E, Extractable. Short headings that name the question, a direct answer under each, tables for comparisons, numbered steps for processes.
- T, Trustworthy. A named author with a linked bio, sourced numbers, and an About and Contact page that state who runs the site.
- C, Crawlable. PerplexityBot allowed, no Cloudflare or firewall rule blocking it, pages that render without JavaScript tricks.
- H, Hyper-relevant answer first. The direct answer to the page's main question in the first 100 words, in a sentence that makes sense on its own.

7 Perplexity SEO steps to get cited
Step 1: Make sure Perplexity can actually reach you
Start with robots.txt: open yourdomain.com/robots.txt and confirm there is no Disallow rule for PerplexityBot. The robots.txt guide for beginners covers the syntax.
Then check the CDN layer. Since 1 July 2025, Cloudflare asks every new domain whether to allow AI crawlers and blocks them by default. Existing customers get a one-click block [5]. A site behind Cloudflare with that setting on is invisible to PerplexityBot, whatever robots.txt says. Log in to Cloudflare, open the AI crawl controls for the zone, and decide deliberately. Anobee runs on Cloudflare with a robots.txt that allows all crawlers, and a request sent with PerplexityBot's user agent on 14 October returned the page normally. Allowing search crawlers while blocking training crawlers is a reasonable middle setting if you want one.
One more thing to know. In August 2025 Cloudflare reported what happened when Perplexity's declared crawlers were blocked. Undeclared crawlers using a generic Chrome user agent and rotating networks fetched the same content anyway, and Cloudflare began blocking that behaviour [4]. Two consequences follow. A robots.txt block is not a reliable way to keep content out of Perplexity. If you want to be cited, an explicit allow is the setting that makes your intent clear.

Verify: fetch your robots.txt, confirm PerplexityBot is not disallowed, and confirm your CDN or firewall is not challenging or blocking it.
Step 2: Rank in Google for the question
Given the 82% URL overlap with Google's top 10 [2], this is the step in Perplexity SEO with the most leverage and the least Perplexity-specific advice. Pick the question a page answers and check the live Google results for it. Then do the ordinary work: match the intent, cover what the top results cover, earn links. The on-page SEO checklist is the list Anobee runs. A page on Google's page three is unlikely to be in Perplexity's retrieval set, however well it is formatted.
Step 3: Answer the question in the first 100 words
Perplexity quotes passages. The passage most likely to be quoted is a self-contained answer near the top of the page, phrased close to the way the question is asked. Write it as one short paragraph, 40 to 60 words, that states the answer before the context. Anobee's CMS renders this as a "Quick answer" block. On WordPress, a bold lead paragraph does the same job.
Step 4: Structure the rest for extraction
Under each heading, put the answer to that heading's question in the first sentence. For Perplexity SEO, that first sentence is the one most likely to be quoted. Use a table wherever two or more things are compared, numbered lists for processes, and definitions stated as definitions ("X is a..."). Avoid long paragraphs that bury the claim in the middle. Google gives the same advice for its own AI features, framed as helping readers rather than machines [7].
Step 5: Make the entity pages unambiguous
Perplexity kept citing Anobee's homepage, and in September its About, Contact and author pages too. Those pages exist to say who is behind the site. Make sure they do: the same name everywhere, a real contact route, an author page with a bio, and consistent facts across the site and your profiles. The entity optimization guide covers the details. If your brand name collides with another company's, as Anobee's does with Amobee, state the distinction on the About page yourself rather than leaving it to the model.
Step 6: Keep pages current, honestly
Freshness correlates with citation in third-party studies, including Analyze AI's [6]. The trap is faking it. Google's people-first content guidance names one form of it directly. Changing a page's date to make it seem fresh, when the content has not substantially changed, is listed among the signs of search-engine-first content [8]. Update pages when facts change, note what changed, and let the date follow the edit. For fast-moving topics like this one, that is roughly monthly. For a how-to that has not changed, it is never.
Step 7: Measure with referrals and a fixed prompt set
Perplexity, unlike ChatGPT, usually passes a referrer. In GA4, go to Reports, then Acquisition, then Traffic acquisition. Set the dimension to Session source / medium and search for "perplexity"; visits appear as perplexity.ai / referral. The GA4 setup guide covers the property side.
Referrals only capture clicks, and many citations never produce one. So run a fixed set of ten to twenty prompts in a fresh Perplexity session each month, and record the source URLs as described above. Keep the prompts identical between runs, because changing them breaks the comparison.
What changed in this guide
The first version of this Perplexity SEO guide carried a weighted "six ranking factors" table, with figures such as "domain authority is 15% of Perplexity's scoring". None of it could be traced to a dataset, so it is gone. It also understated how closely Perplexity tracks Google, which Semrush's overlap data contradicts [2]. And it treated robots.txt as the whole crawlability story, which Perplexity's documentation and Cloudflare's reports do not support [1][4][5].
This October update adds the fourth test run, the section on tracking source URLs, and Perplexity's move from Sonar to the Agent API.
Bottom line on Perplexity SEO
Perplexity SEO is mostly SEO. Rank in Google for the question, and make sure PerplexityBot and your CDN are not standing in the way. Put the answer at the top of the page and keep your identity pages consistent. Then measure with a fixed prompt set and the Links tab, because a Perplexity citation is a snapshot. Anobee was cited in all four runs and kept at most two of the same pages between them. If ChatGPT is the next engine you want to be cited in, how to get cited by ChatGPT covers where its behaviour differs.
Frequently Asked Questions
What is Perplexity SEO?
Perplexity SEO is the practice of making a page eligible, retrievable and easy to cite in Perplexity's generated answers. Perplexity does not show a ranked list; it writes one answer and attaches source links. The work is being crawlable, ranking well in Google (which Perplexity's retrieval tracks closely), and stating answers clearly enough to be quoted.
Does Perplexity use Google rankings to choose sources?
Not officially, but its results track Google closely. Semrush's July 2025 study of 5,000 keywords found Perplexity's cited sources had over 91% domain overlap and 82% URL overlap with Google's top 10, far higher than Google AI Mode or ChatGPT. Strong Google rankings are the most reliable path into Perplexity's source set.
Does blocking PerplexityBot in robots.txt keep my site out of Perplexity?
It keeps you out of PerplexityBot's index, which Perplexity says surfaces sites in its search results. It does not stop Perplexity-User, which fetches a page when a user asks a question and, according to Perplexity's documentation, generally ignores robots.txt. Cloudflare has also reported undeclared Perplexity crawlers evading blocks.
How do I see which URLs Perplexity cited?
Open the Links tab above the answer. It lists every source Perplexity used, each with its full URL. The small chips in the answer text group sources, and a chip marked +1 or +3 holds more than one. At scale, Perplexity's Agent API returns source URLs in a search_results item.
Can a new or small site get cited in Perplexity?
Yes. Anobee, a site that began publishing in mid-2026, was cited by Perplexity in all four runs of its fixed-prompt test between September and October 2026, with 4 to 11 Anobee pages per run. The pages changed almost completely between runs, so treat a citation as a snapshot, not a position you hold.
How do I track Perplexity traffic in Google Analytics?
In GA4, open Reports, then Acquisition, then Traffic acquisition, set the dimension to Session source / medium and search for perplexity. Perplexity passes perplexity.ai as the referrer, so visits appear as perplexity.ai / referral. For citations that never turn into clicks, run a fixed set of prompts monthly and record which pages appear.
Sources and References
- Perplexity: Perplexity Crawlers (developer documentation) ↩
- Semrush: How Google's AI Mode Compares to Traditional Search and Other LLMs (AI Mode Study) ↩
- TechCrunch: Perplexity received 780 million queries last month, CEO says ↩
- Cloudflare: Perplexity is using stealth, undeclared crawlers to evade website no-crawl directives ↩
- Cloudflare: Content Independence Day, no AI crawl without compensation ↩
- Analyze AI: Perplexity AI Ranking Guide, What Drives Citations ↩
- Google Search Central: Optimizing your website for generative AI features on Google Search ↩
- Google Search Central: Creating helpful, reliable, people-first content ↩
- Perplexity: Migrate from Sonar to the Agent API ↩
Was this guide helpful?
Your answer helps Anobee improve future updates.
Written by
Bibek Thapa
AI-Powered Digital Growth Strategist
Bibek Thapa works across AI workflows, SEO, AI search optimization, content strategy, website growth, and productivity systems at Anobee.
- AI workflows
- Digital growth
- SEO
- GEO
- AEO
- Content strategy
- Website growth